Workflows
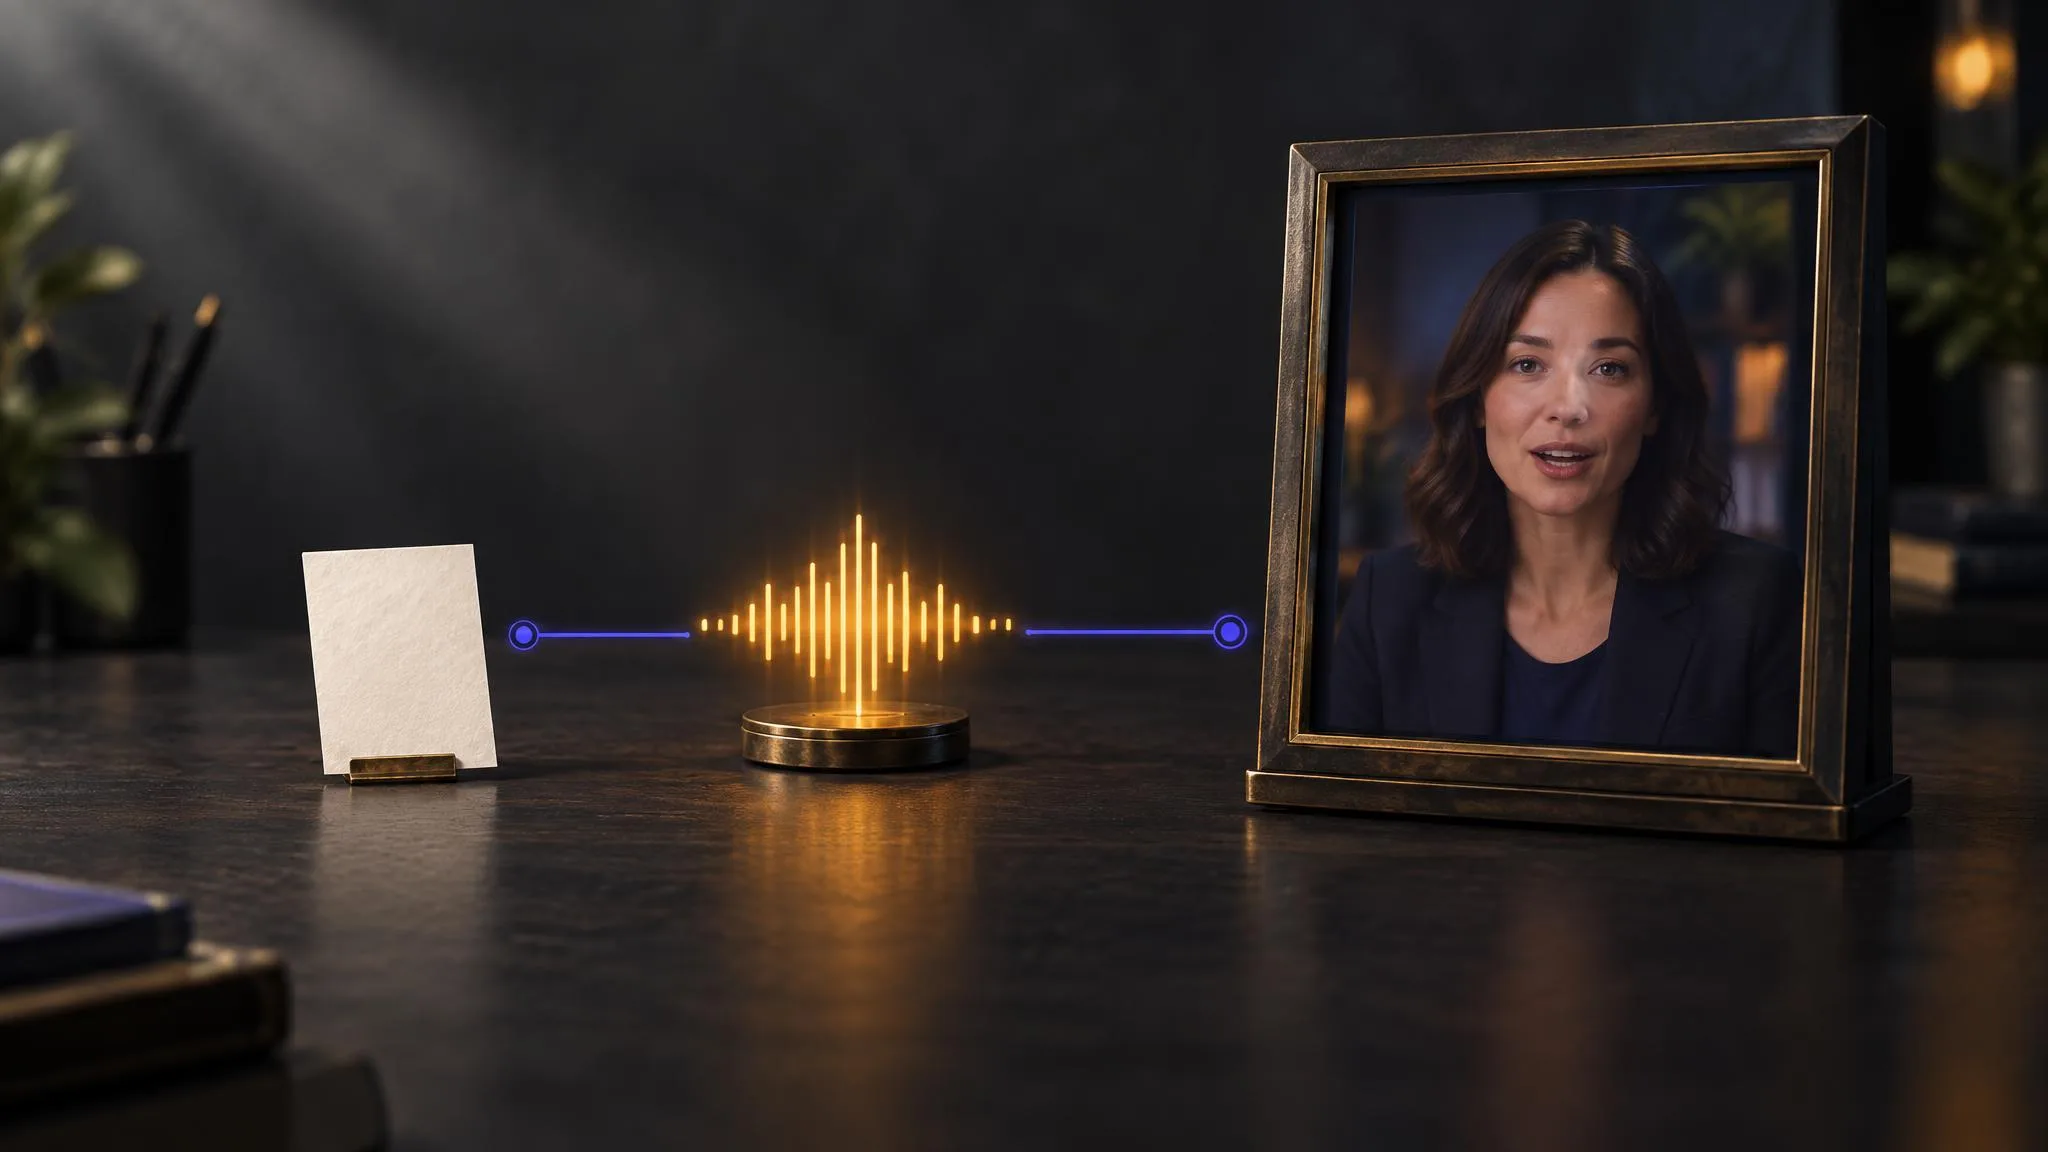
From a written script to a talking presenter: text-to-speech, then lip-sync
Two generations turn a script into a presenter: a voice model reads the text, then a lip-sync model puts that audio on a face. The voice step is cheap enough to redo a dozen times; the face step is not. Here is the order that saves the credits, with measured numbers.